Partitioning/Sharding
Sharding separates large databases into smaller, more easily managed
parts called shards. Each shard shares the same schema, though the
actual data on each shard is unique to the shard.
Why Patitioning is needed?
To spread the data and the query load evenly across nodes/shards.
For a system having 10 shards, If every node takes a equal share, then
a system will handle 10 times the read and write throughput compared
to 1 node system.
Advantages of Sharding:
1. Scalability: Sharding allows horizontal scaling by
distributing data across multiple database instances, enabling the
system to handle increased traffic and data volume.
2. Performance: By distributing data across shards, queries can
be executed in parallel, reducing response times and improving overall
performance.
3. Fault Isolation: If one shard experiences issues or
failures, it does not affect the entire system, assuming replication
is also done.
Issues in Sharding
1. Hotspot. All data goes to 1 shard
Problem: Some partitions/shards have more data or queries than
others. In an extreme case, all the load could end up on 1 partition,
so 9 out of 10 nodes are idle
Solution:
1. Resharding: Add more shards and redistribute data among
shards to balance load.
2.
Consistent Hashing
2. Distributed Join
It is hard to perform join operations across database shards.
Complexities
1. Scatter-Gather Overhead: To join data that lives on
different shards, the application must issue multiple independent
queries across network boundaries, drastically increasing latency
2. Fetching, Filtering, Gathering: After fetching data from
multiple shards, the application needs to filter and gather the
relevant information, adding additional complexity and overhead.
3. Distributed Transactions: Ensuring consistency across
multiple shards during writes or complex updates requires expensive
distributed transaction protocols like Two-Phase Commit (2PC), which
heavily penalize throughput.
Sharding/Partition key
Example: User data is allocated to a database server based on
user IDs, a hash function is used to find the corresponding shard.
Determine how data is distributed. In this example (key =
user_id % 4)
Criteria is to choose a key that can evenly distributed data
partition_id = hash(user_id) % number_of_shards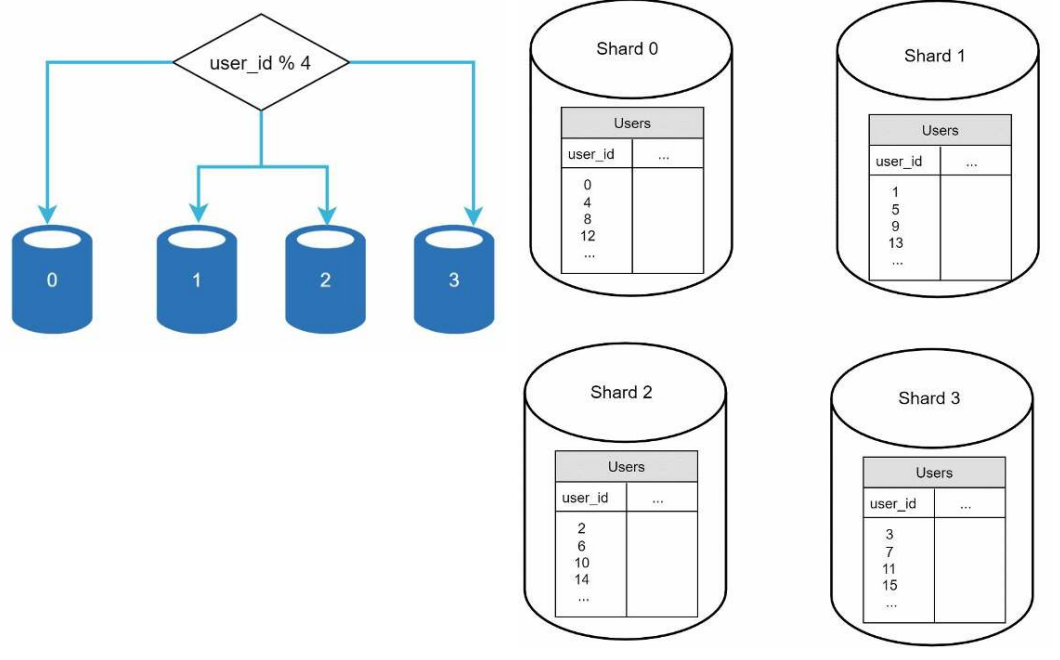
Key Considerations for Sharding Keys
1.
Region based Partition / Sharding based on location IDs
Storing data specific to region (maybe based on pin code).
Advantages:
1. Data Localization: Users in a particular region primarily access
data relevant to that region, which can reduce latency and improve
response times.
2. Regulatory Compliance: Data privacy laws may require certain data
to be stored within specific geographic regions
3. Disaster Recovery: In the event of a localized failure or disaster,
having region-based partitions can make it easier to implement
disaster recovery strategies. We can focus on recovering data for
specific regions without affecting the entire system
How Application talks to shards
Database drivers(such as Diesel's) run directly on the application
side.
Application 1st calculates the shardId then using Diesel(or other)
explicitly communicates to database shards